
Clustered assignment
Randomize at the right level
Start with the assigned population
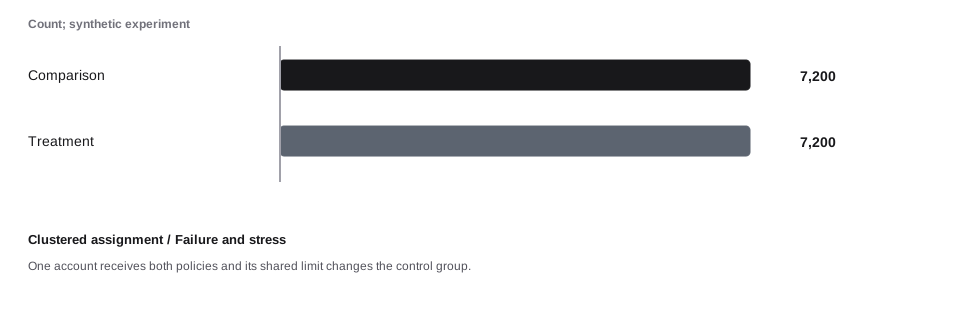
This teaching experiment assigns 7,200 eligible units to comparison and 7,200 to treatment. The units are account clusters. Mandatory controls are outside the experimental choice. Eligibility and assignment are defined before observing outcomes.
Figure data and text version
| Assigned arm | Units |
|---|---|
| Comparison | 7,200 |
| Treatment | 7,200 |
Related transactions can influence each other through shared limits, devices, and review decisions. Row-level assignment may contaminate both treatment groups.
One account receives both policies and its shared limit changes the control group.
All amounts, rates, capacity limits, and outcomes in this case are synthetic. The three conditions are separate assumptions for comparison. A better result in the response condition is not measured proof that the proposed control causes that improvement. The figures expose the calculation and its limits; a real deployment needs its own evidence.
Read the result
The comparison arm has 449/7200 adverse outcomes (6.24%) and the treatment arm has 501/7200 (6.96%). The absolute difference is 0.72 percentage points, with an illustrative large-sample 95% interval from -0.09 to 1.53. Interpretation depends on assignment integrity, outcome maturity, independence, and the actual decision being evaluated.
Model inputs and calculated values
Inputs below are the case-specific values. Each figure states the condition-specific assumptions and units used in its calculation. Calculated values are rounded for display.
| Input | Value |
|---|---|
| population | 14,400 |
| clusterSize | 18 |
| correlation | 0.11 |
| rate | 0.048 |
| Calculated value | Result |
|---|---|
| n | 14,400 |
| nc | 7,200 |
| nt | 7,200 |
| yc | 449 |
| yt | 501 |
| effect | 0.0072 |
| lower | -0.0009 |
| upper | 0.0153 |
| clusterSize | 18 |
| icc | 0.528 |
| effectiveN | 1,443.4643 |
Retain events and nonevents in both arms
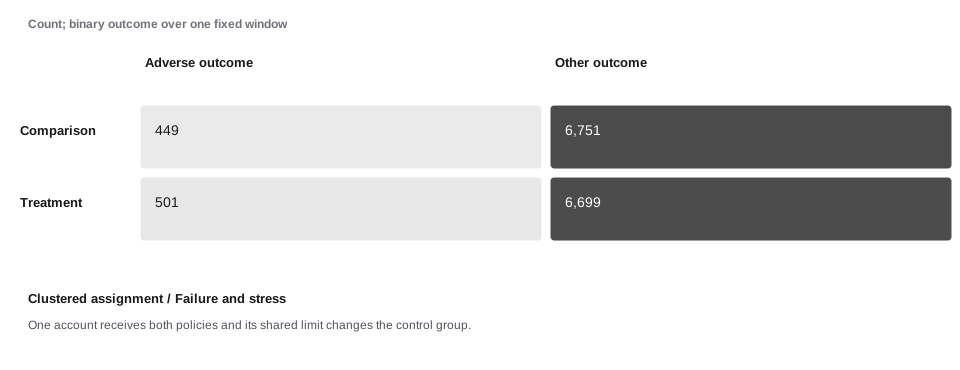
The defined adverse outcome occurs 449 times in comparison and 501 times in treatment. Each row includes every assigned unit under this complete-outcome illustration. Omitting nonevents or unresolved cases changes the denominator and the estimand.
Figure data and text version
| Assigned arm | Adverse outcome | Other outcome |
|---|---|---|
| Comparison | 449 | 6,751 |
| Treatment | 501 | 6,699 |
Absolute and relative effects answer different questions
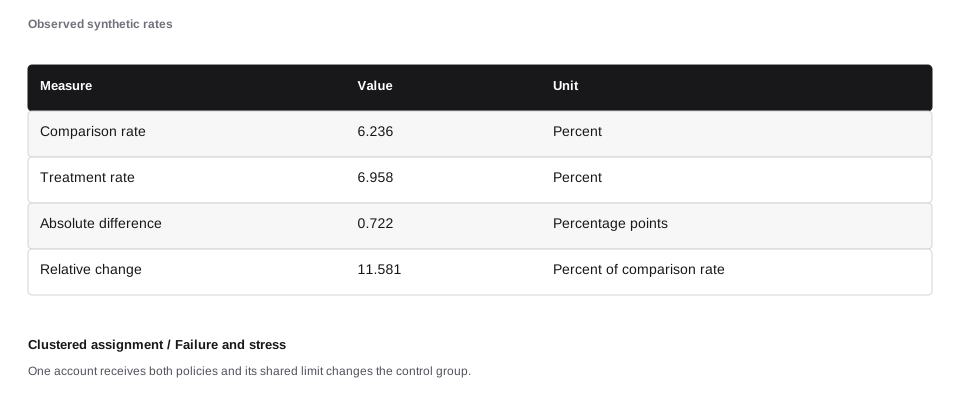
Treatment minus comparison is 0.72 percentage points. The relative change is 11.58% when the comparison rate is nonzero. A percentage-point difference and a percentage change must not share the same label.
Figure data and text version
| Measure | Value | Unit |
|---|---|---|
| Comparison rate | 6.236 | Percent |
| Treatment rate | 6.958 | Percent |
| Absolute difference | 0.722 | Percentage points |
| Relative change | 11.581 | Percent of comparison rate |
Each arm’s rate has sampling uncertainty
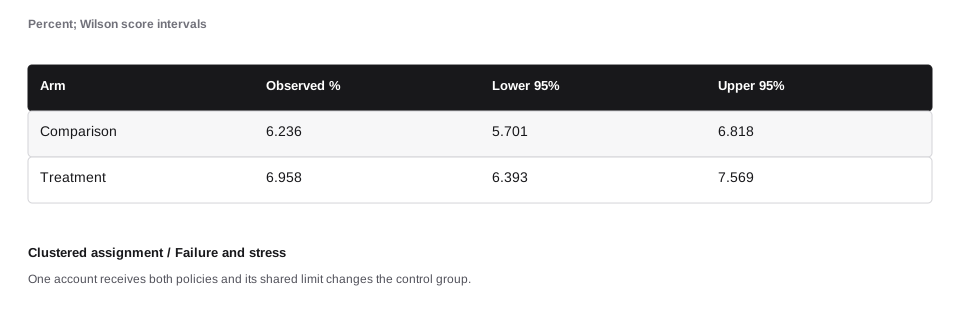
The 95% Wilson intervals are [5.70, 6.82]% and [6.39, 7.57]%. These intervals use independent Bernoulli sampling assumptions. Shared customers or merchants can violate that independence and require an appropriate clustered analysis.
Figure data and text version
| Arm | Observed % | Lower 95% | Upper 95% |
|---|---|---|---|
| Comparison | 6.236 | 5.701 | 6.818 |
| Treatment | 6.958 | 6.393 | 7.569 |
Uncertainty in the difference
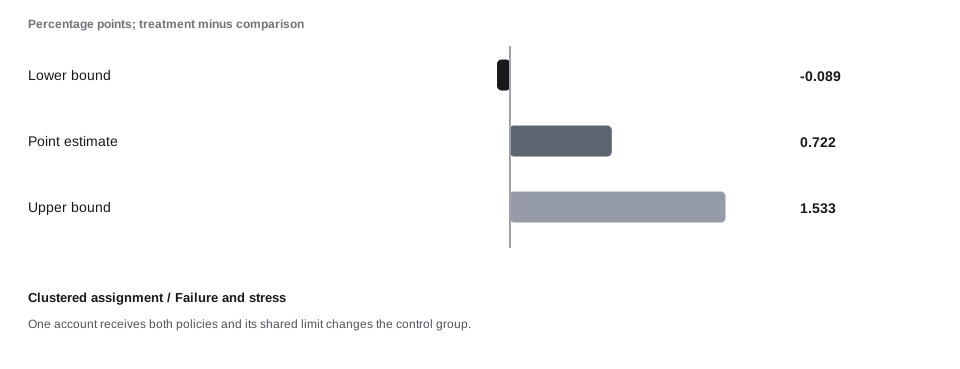
The normal-approximation 95% interval for treatment minus comparison is [-0.09, 1.53] percentage points. It is a teaching large-sample interval, not a replacement for the analysis appropriate to the design, low counts, sequential monitoring, or multiple comparisons.
Figure data and text version
| Difference measure | Percentage points |
|---|---|
| Lower bound | -0.089 |
| Point estimate | 0.722 |
| Upper bound | 1.533 |
A fixed outcome horizon prevents premature comparison
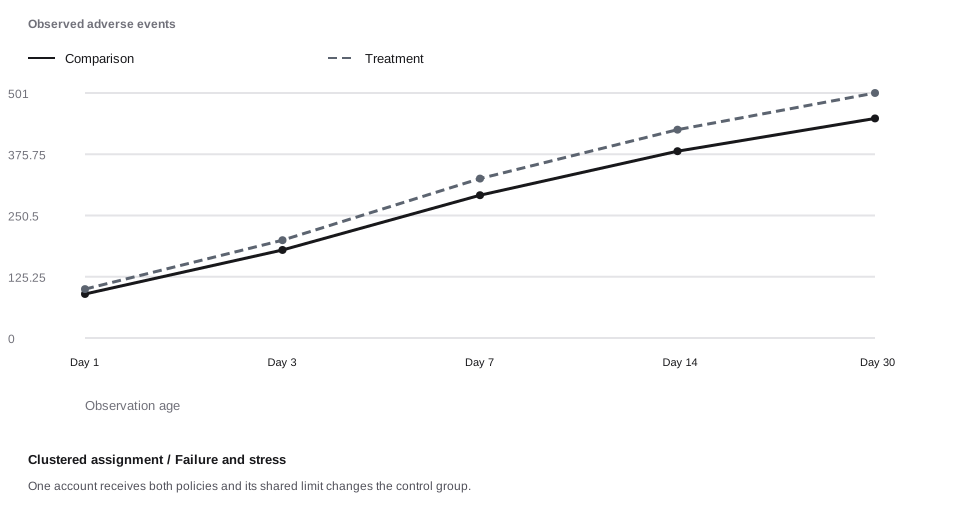
Both arms use the same explicitly constructed maturation fractions. Earlier data can undercount the final outcome even when assignment is correct. Stopping at the first favorable partial result also changes the statistical interpretation unless the monitoring design accounts for it. Horizontal positions are the labeled observations or scenarios; equal spacing does not imply equal numerical increments.
Figure data and text version
| Observation age | Comparison events | Treatment events |
|---|---|---|
| Day 1 | 90 | 100 |
| Day 3 | 180 | 200 |
| Day 7 | 292 | 326 |
| Day 14 | 382 | 426 |
| Day 30 | 449 | 501 |
Assignment and received treatment differ
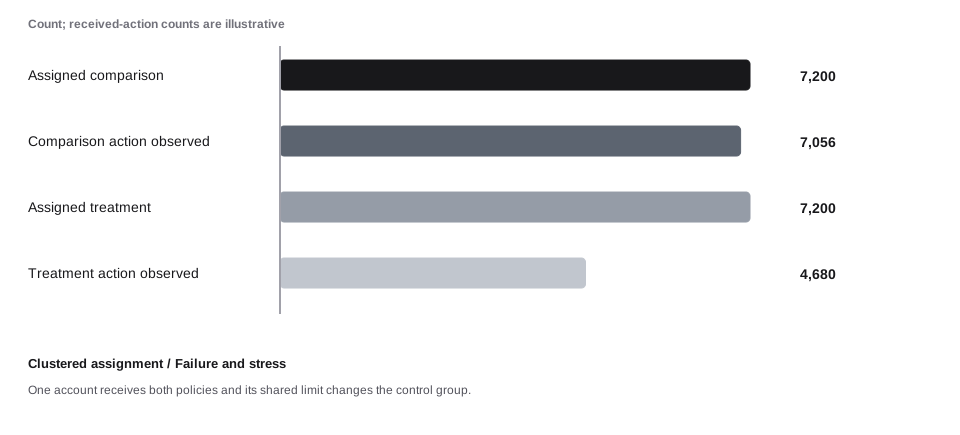
7200 units are assigned to treatment, while 4680 receive the modeled action. The primary assignment-based comparison retains all assigned units. Restricting to action recipients selects a post-assignment subgroup and can introduce bias.
Figure data and text version
| Population | Units |
|---|---|
| Assigned comparison | 7,200 |
| Comparison action observed | 7,056 |
| Assigned treatment | 7,200 |
| Treatment action observed | 4,680 |
Correlated units reduce independent information
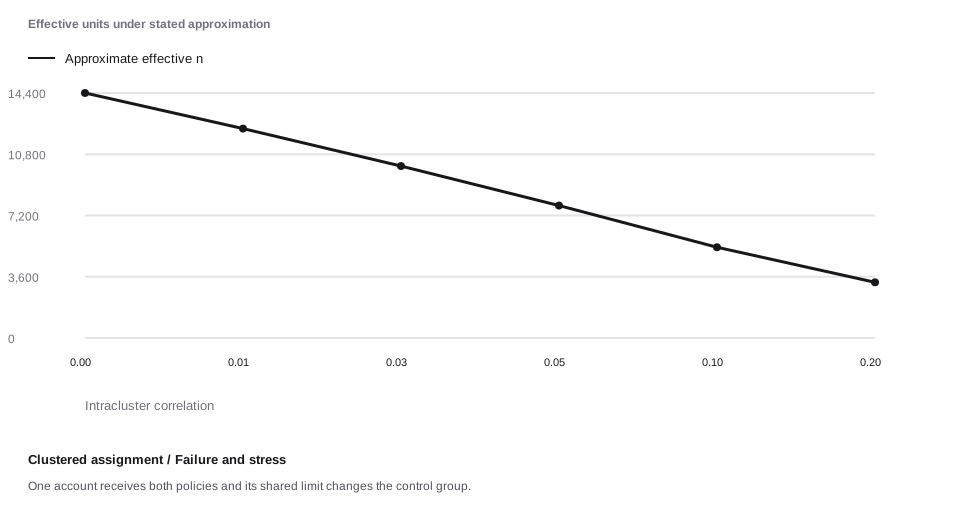
The design-effect illustration is 1 + (m − 1)ρ with cluster size m = 18. At the case’s assumed ρ = 0.528, the design effect is 9.976 and n/design-effect is about 1,443.5. This approximation assumes a simple equal-cluster design; it is not a universal effective-sample-size formula. Horizontal positions are the labeled observations or scenarios; equal spacing does not imply equal numerical increments.
Figure data and text version
| Intracluster correlation | Approximate effective n |
|---|---|
| 0.00 | 14,400 |
| 0.01 | 12,307.7 |
| 0.03 | 10,105.3 |
| 0.05 | 7,783.8 |
| 0.10 | 5,333.3 |
| 0.20 | 3,272.7 |
Segment totals must reconcile to the whole
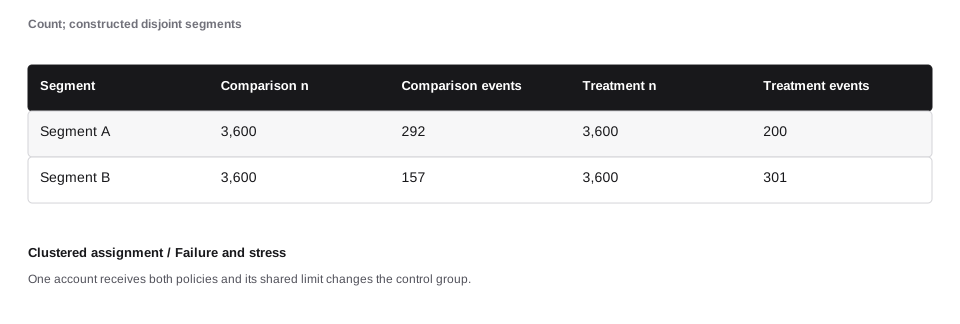
The two synthetic segments partition each arm. Their outcome counts add back to the original totals. Segment effects can differ from the overall effect, but small cells, selection, and multiple comparisons must be considered before interpreting a subgroup result.
Figure data and text version
| Segment | Comparison n | Comparison events | Treatment n | Treatment events |
|---|---|---|---|---|
| Segment A | 3,600 | 292 | 3,600 | 200 |
| Segment B | 3,600 | 157 | 3,600 | 301 |
The primary outcome is only one decision input
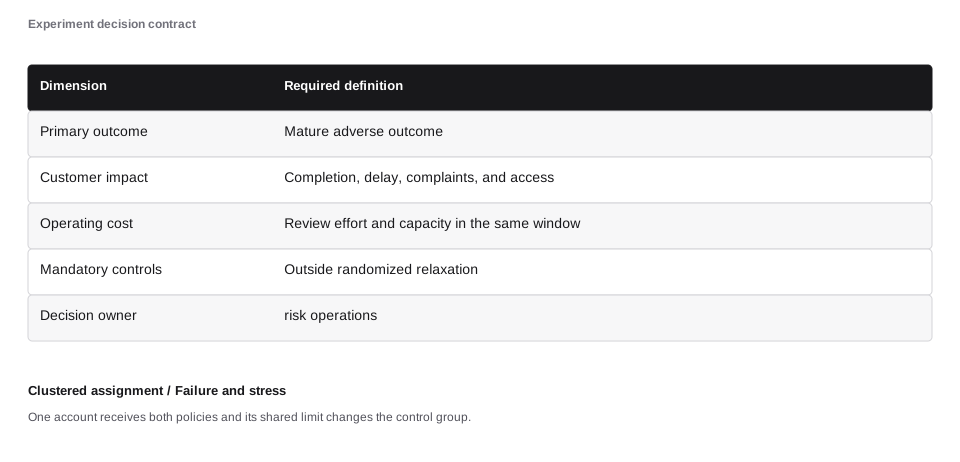
The primary target is Mature adverse outcome. A release also considers customer friction, queue capacity, required controls, and the uncertainty of the result. A favorable loss metric cannot justify an action that violates a separate obligation.
Figure data and text version
| Dimension | Required definition |
|---|---|
| Primary outcome | Mature adverse outcome |
| Customer impact | Completion, delay, complaints, and access |
| Operating cost | Review effort and capacity in the same window |
| Mandatory controls | Outside randomized relaxation |
| Decision owner | risk operations |
Specify the analysis before observing the result
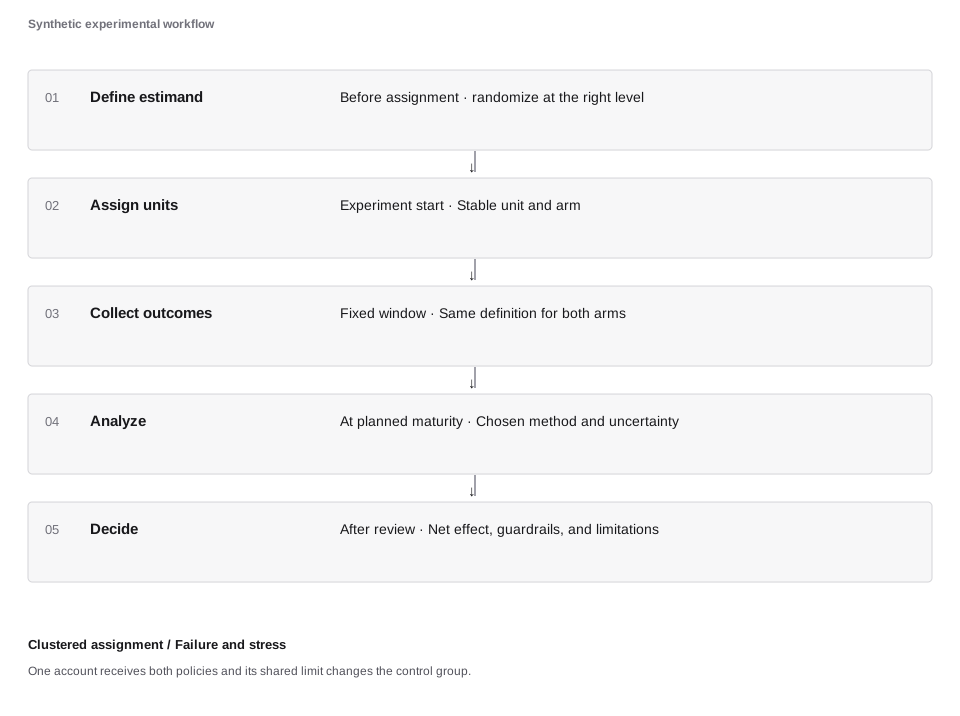
The protocol fixes assignment, exclusions, metrics, outcome maturity, and the comparison method. Changing these after seeing results can make an ordinary noise fluctuation look like an improvement. Amendments need a documented reason and a clear distinction between confirmatory and exploratory work.
Figure data and text version
| Stage | Timing | Record |
|---|---|---|
| Define estimand | Before assignment | randomize at the right level |
| Assign units | Experiment start | Stable unit and arm |
| Collect outcomes | Fixed window | Same definition for both arms |
| Analyze | At planned maturity | Chosen method and uncertainty |
| Decide | After review | Net effect, guardrails, and limitations |
What this example establishes and omits
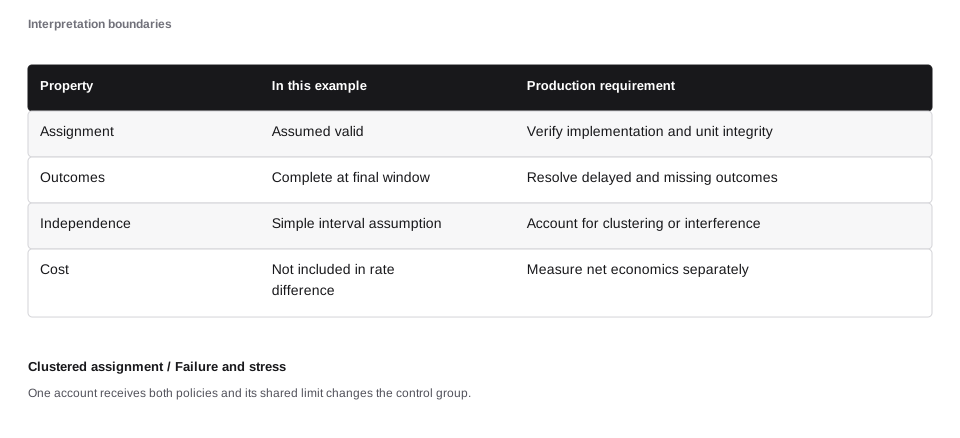
The arithmetic shows how the stated counts become rates, differences, and intervals. It does not prove a causal effect in production. Causal interpretation requires a valid assignment process, appropriate handling of interference and missing outcomes, and analysis consistent with the design.
Figure data and text version
| Property | In this example | Production requirement |
|---|---|---|
| Assignment | Assumed valid | Verify implementation and unit integrity |
| Outcomes | Complete at final window | Resolve delayed and missing outcomes |
| Independence | Simple interval assumption | Account for clustering or interference |
| Cost | Not included in rate difference | Measure net economics separately |
Connect the result to the system
Assign at a defensible entity boundary and account for dependence in uncertainty estimates.
Check the population, evidence, permitted action, and actual effect together. A balanced calculation can still use the wrong population; a successful response can still leave an unknown financial outcome. The case’s numerical result applies only to its stated assumptions.
Sources and further reading
The chapter sources support the concepts and scope. They do not prescribe the synthetic model rates.